Running Llama on Tenstorrent AI Accelerator vs NVIDIA GPU
Summarized by VidSnap AI from Compiled by Stas on YouTube · Feb 10, 2026 · Watch the original
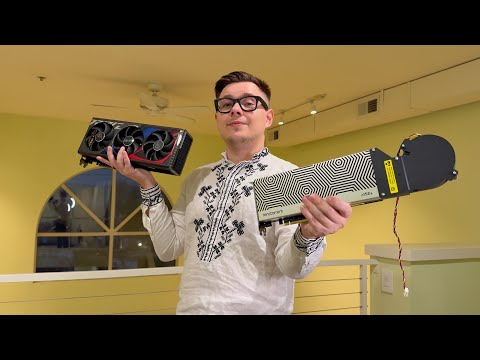
The video provides a compelling comparison of running the Llama 3 8B Instruct model on cutting-edge Tenstorrent AI accelerator hardware (N150) against a traditional NVIDIA GPU (RTX 4090), aiming to evaluate and contrast their performance in LLM inference tasks. 🚀 This evaluation is critical for organizations considering optimal hardware for scalable and cost-effective AI deployments.
For the NVIDIA setup, the Llama 3 8B Instruct model was served using vLLM within a plm-cuda virtual environment, requiring a manual Torch installation to ensure robust CUDA support. The model was configured with a max-model-len of 4096 and made accessible via an OpenAI-compatible API on port 80001. 🛠️ Conversely, the Tenstorrent setup involved cloning the Dev branch of VM Ripper, executing specific setup scripts from the TT-metal directory, and downloading model weights directly from Meta. The server example was then run on an N150 device, exposed on port 8000, also offering an OpenAI-compatible API.
Performance testing involved a Jupyter Notebook sending an identical query: "Help a developer to debug application hello generate a variable on Text I'm testing API and performance," with a strict limit of 500 output tokens and a temperature of 0. The results revealed a notable difference in raw inference speed:
- NVIDIA RTX 4090: Achieved a response in 8.6 seconds. ⏱️
- Tenstorrent N150: Completed the same task in 19 seconds.
While the NVIDIA 4090 demonstrated superior raw speed in this single test, a crucial cost-performance analysis presented a more nuanced picture. With the NVIDIA 4090 priced at approximately $2,000, compared to the Tenstorrent N150 at $1,000 and the M300 (estimated) at $1,400, the performance per dollar metric showed all three platforms to be highly competitive, with Tenstorrent's M300 potentially offering a slight edge.
Final Takeaway: This initial benchmark, while not exhaustive, underscores that while NVIDIA currently leads in raw single-test performance for LLM inference, Tenstorrent is rapidly closing the gap in cost-effectiveness. 💰 The comparable or even superior performance per dollar offered by Tenstorrent accelerators positions them as a compelling alternative for enterprises seeking to optimize AI infrastructure budgets. As the AI hardware landscape evolves, Tenstorrent's competitive pricing and developing capabilities warrant significant attention from businesses evaluating their long-term AI strategy and seeking alternatives to established market leaders. This dynamic market promises continued innovation and improved options for LLM deployment.
Want to summarize your own videos?
Try VidSnap free